Mascot for Data Independent Acquisition (DIA)
Mascot DIA is a spectrum-centric approach for identifying and quantifying proteins from Data Independent Acquisition (DIA) runs. It is built on three products: Mascot Distiller (preprocessing and quantitation), Mascot Server (high-throughput identification) and Mascot Daemon (automation).
In DIA, the mass spectrometer runs a survey scan (MS1), followed by sequentially isolating and fragmenting several m/z ranges (MS2). The cycle repeats at regular intervals until the end of the LC gradient. Each MS2 spectrum is a convolution of fragments from several precursors with similar m/z and retention time. The principle has been refined into dozens of acquisition schemes; see Acquisition and Analysis of DIA-Based Proteomic Data: A Comprehensive Survey in 2023, Mol Cell Proteomics 23(2):100712 (2024).
The advantage of DIA is, precursors are sampled without bias, because everything in an isolation window is selected for fragmentation, in a data independent manner. However, peptides become more difficult to identify. An alternative to DIA is Data Dependent Acquisition.
Mascot supports both DDA and DIA.
Why should I use Mascot for DIA?
Mascot DIA is ideal for untargeted and discovery proteomics, because it has no limits.
- Use any sequence database, from a single proteome to the entire UniProt database (hundreds of millions of sequences).
- Use any variable modifications from Unimod (~1500 mods) or add your own.
- Use any enzyme or search for semi-tryptic or endogenous proteins.
- Use any quantitation method based on MS1 signal – label-free quantitation, SILAC, 18O, metabolic.
- High-throughput client-server architecture – any number of client programs can use the same protein identification server.
Mascot is ideal for DIA because of its reliability.
- Universal probabilistic scoring – works with any instrument and acquisition strategy.
- Universal peak detection – works with any instrument and is independent of machine learning.
- Peptide identifications are inherently reliable – Mascot will not report a match unless it has statistically unambiguous fragmentation evidence.
- Protein identifications are inherently reliable – every protein hit must have unique peptide evidence.
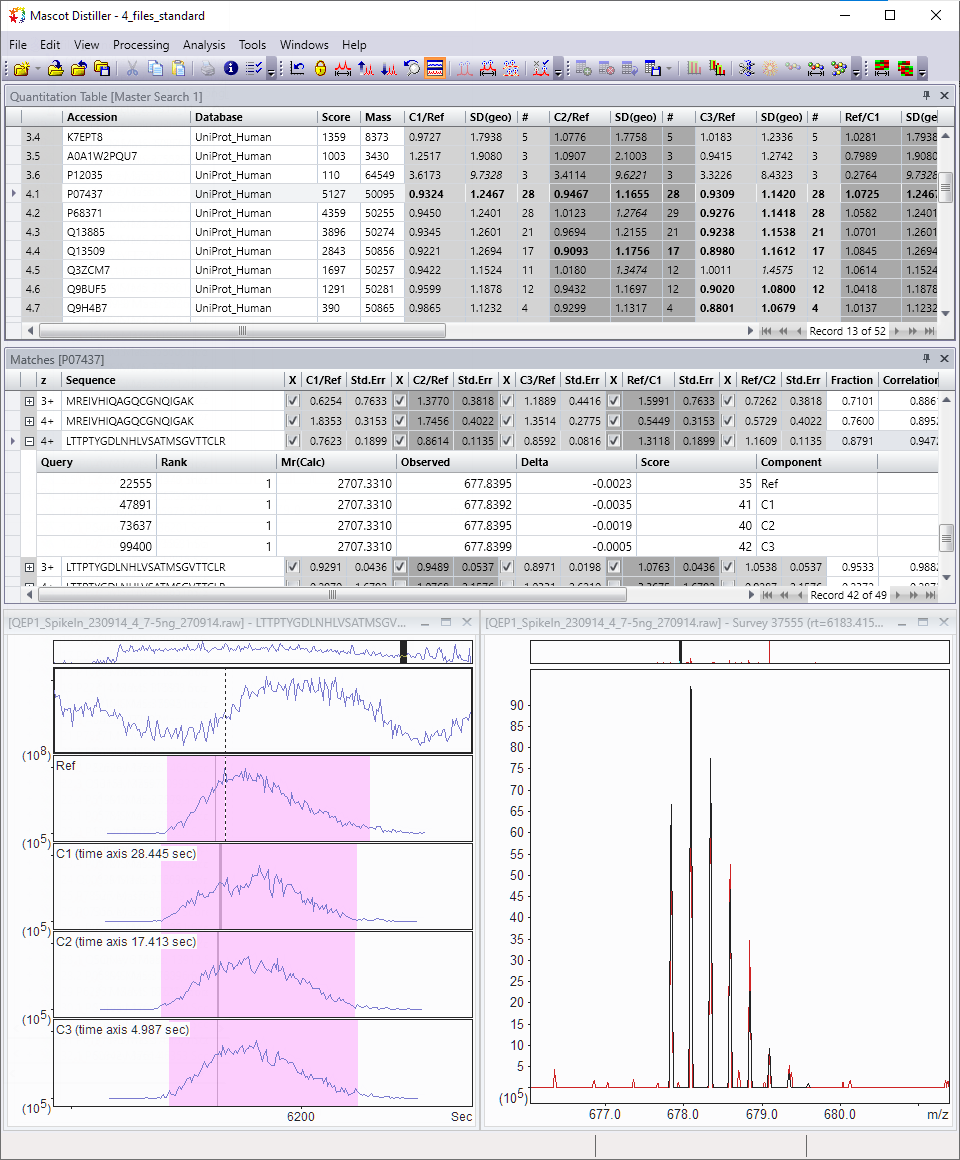
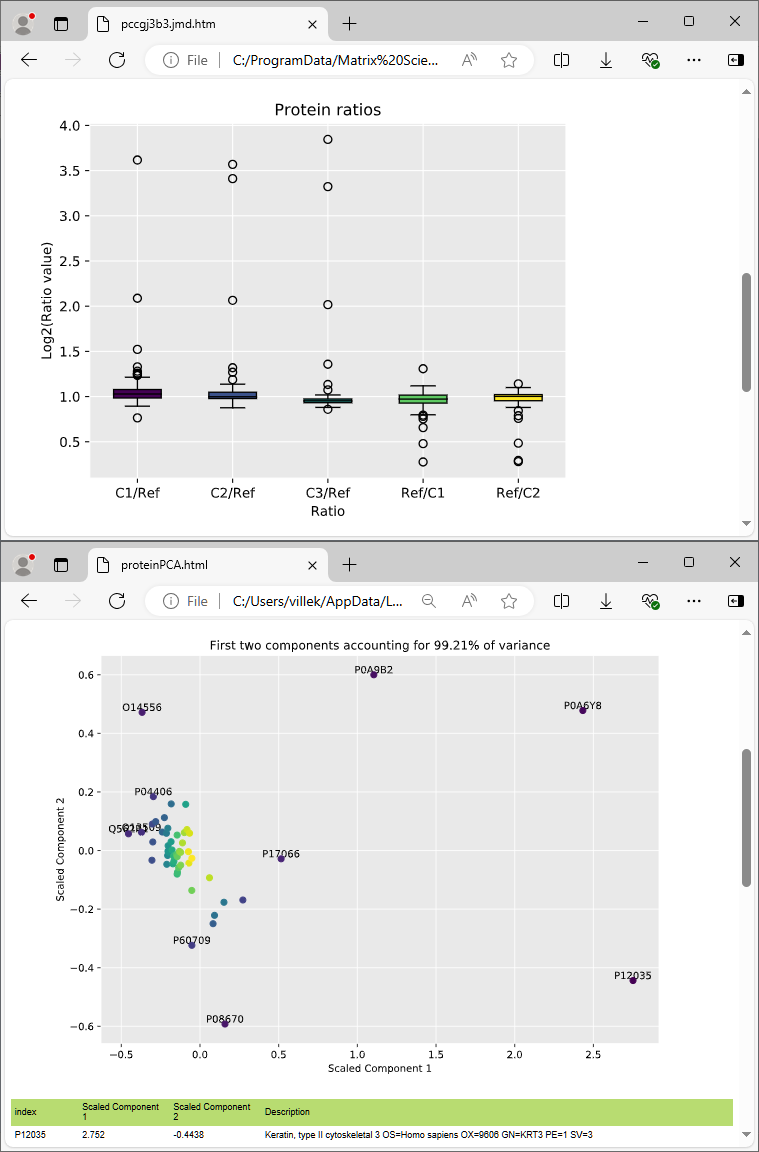
Don’t just take our word for it. Drill down in the interactive reports to inspect the MS/MS spectral evidence, XICs and time alignment results. A number of quantitation and quality reports are included out of the box.
What do I need to get started?
You need Mascot Distiller 3.0 or later. Please contact us for a trial licence. If you have an existing Mascot Distiller 2.x licence, please contact us for pricing or get a quote.
You also need Mascot Server 3.2 or later. If you have an earlier version or your support contract has lapsed, please contact us for pricing or get a quote.
Which instruments are supported?
Mascot DIA currently supports Thermo Orbitrap instruments, SCIEX instruments and Waters MSE:
- Any Thermo Orbitrap instrument that saves the acquisition in a Thermo Xcalibur raw file is supported. This includes Thermo Orbitrap Astral.
- Any SCIEX instrument that saves the acquisition in a wiff file is supported. This includes QTOF systems (e.g. ZenoTOF 7600, 8600) and TripleTOF systems (e.g. 6500+).
- Any Waters instrument where data are acquired using MSE.
Support for Bruker diaPASEF is planned.
The acquisition strategy (SWATH, IDA, etc.) and gradient length do not matter, although you should avoid very short (<10min) gradients. We recommend an isolation window width between 2Th and 8Th. Isolation windows may be staggered or overlapped in any configuration.
Mascot DIA can identify peptides from MS/MS scans with a wider isolation window (>8Th), but the larger the window, the lower the sensitivity. With wider isolation windows, ion mobility separation is strongly recommended. Alternatively, use a longer gradient.
Mascot also supports DDA analysis, including all Agilent, Bruker, SCIEX, Shimadzu, Thermo and Waters instruments commonly used in proteomics.
What is the Mascot DIA LFQ workflow?
The Mascot DIA LFQ workflow is exactly the same as the Mascot DDA LFQ workflow:
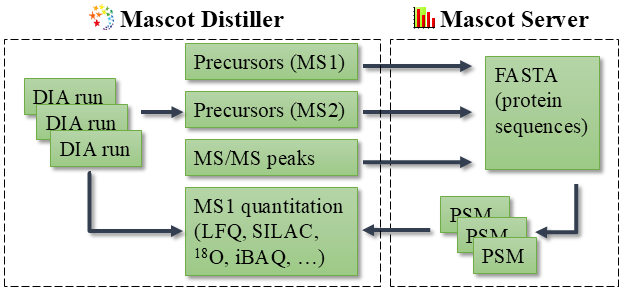
Mascot Distiller reads vendor raw files, processes the MS/MS spectra into peak lists and determines potential precursor masses for each MS/MS spectrum. Precursors are detected from MS1 survey scans as well as from MS2 scans using a novel algorithm. Distiller submits the peak lists to Mascot Server for identification by database searching.
Mascot Server tries to match peptides from a protein sequence database against the observed MS/MS spectrum. Candidate sequences within precursor tolerance are matched independently to the spectrum, allowing multiple precursors to match simultaneously. Mascot calculates a probabilistic match score for each match. At the end of the search, matches are rescored in multiple dimensions using Percolator, and optionally predicted fragment intensities (MS2PIP) and retention time (DeepLC).
Mascot Distiller imports the identified peptides and proteins, and calculates the extracted ion chromatogram (XIC) for each peptide from MS1 signal. Multiple runs are aligned in the time dimension based on shared peptide matches. Peptides not identified in the database search may be identified using precursor mass and accurate retention time (“match between runs”). Finally, protein quantitation ratios are calculated from the XICs.
Mascot Daemon automates all steps of preprocessing, database searching and quantitation.
Does Mascot DIA support MS1 or MS2 quantitation?
Mascot Distiller implements a range of MS1 and MS2 quantitation methods.
For DIA quantitation, only MS1 methods are supported. This includes label-free methods (LFQ) and any chemistry that creates a precursor mass shift (18O, metabolic, SILAC, etc.). Mascot Distiller does not currently support label-free quantitation based on the MS2 signal of fragment peaks.
For MS2 quantitation, we recommend using DDA and MS2 methods based on reporter ions: TMT, TMTpro and iTRAQ.
What is spectrum-centric analysis?
DIA software packages can be divided into spectrum-centric and peptide-centric approaches. Mascot DIA is spectrum-centric. The strategies are complementary, with different advantages and disadvantages.
The goal of spectrum-centric identification is to explain as many peaks in the MS/MS spectrum as possible. The peptide that best explains the peaks is reported as the best identification if a statistically significant number of theoretical fragment masses match to the observed peaks.
Advantages of spectrum-centric searching:
- Peptide identification requires a strong run of fragment ions, which increases identification reliability and confidence.
- There are no limits on sequence database size, number of variable modifications or enzyme.
- Works with any instrument and any ion series (a, b, c, x, y, z, z+1).
- Uses all the information in the spectrum, including neutral losses, for PTM localisation.
- Mascot DIA does not require a spectral library or a predicted library: peptide identification is independent of machine learning.
Disadvantages:
- Requires a narrow isolation window, ideally 2m/z to 8m/z. With wider windows, or very short gradients, ion mobility separation is highly recommended. The more complex the spectrum, the fewer peptides can be reliably identified.
- If a precursor has no MS1 signal and its mass cannot be inferred from the MS/MS spectrum, then it cannot be identified.
- If a precursor produces only a few fragments, it cannot be confidently identified.
What is peptide-centric analysis?
Mascot DIA is spectrum-centric, but many competing products are peptide-centric.
The goal of peptide-centric identification is to find some evidence for a theoretical precursor in the LC-MS/MS run(s). A peptide is identified by tracing the elution of key fragment peaks.
Advantages of peptide-centric searching:
- Supports wide isolation windows (>8m/z) and potentially very complex MS/MS spectra.
- Theoretical precursors may be detected from sequential MS/MS scans even if there is no MS1 signal.
Disadvantages:
- Peptide-centric tools rely heavily on accurate retention time prediction, because the list of theoretical precursors is built from the expected retention time.
- Peptide-centric tools rely heavily on accurate spectral libraries, whether it’s DDA spectra or predicted spectra from a machine learning model.
- Unless the error rate is carefully controlled, peptide-centric tools may claim to identify a peptide from as few as 3-5 fragments.
- Limited to a handful of PTMs and enzymes.
What kind of PC hardware does Mascot DIA require?
DIA data is inherently complex and data sets are large. DIA database searches are typically 3-5 times larger than DDA database searches.
We recommend a Medium Mascot Server licence and an AMD Ryzen 9 or Threadripper processor with 16-32 cores, or equivalent Intel Xeon Gold or Core i9 processor. Choose a processor with high clock speed (>4GHz) as performance per core determines the database search duration and peak picking performance. You should have 64GB RAM and at least 2TB of fast disk space (NVMe).
You can run Mascot Server and Mascot Distiller on the same PC or different PCs. Mascot Server and Mascot Distiller run on the CPU and do not require a GPU.
For more details, see PC specification for Mascot Server and PC specification for Mascot Distiller.